A few weeks ago, I concluded that AI wasn't ready to analyze primary evaluation data and write the report for me. But many of you challenged me to keep looking for places where AI could make an evaluator's work faster and better.Challenge accepted. For my second experiment, I gave four AI models the same literature review assignment.
ChatGPT Plus (GTP 5.5, paid), Claude Cowork (Claude Sonnet 5, paid), Gemini Notebook (Gemini 3.5, free), and SuperGrok (Grok 4.5, paid) were all given the same prompt to search out free articles from specific websites, download those articles for later reference, and summarize them in a lit review using my iEval report template. Then I compared their outputs side-by-side looking at compliance and overall quality.
Want to replicate my experiment? Here’s my actual prompt:
“Look for free articles related to impacts of afterschool programs on youth, families, and school communities (including what has the most positive impacts) at these websites: https://scholar.google.com, http://eric.ed.gov, http://DOAJ.org, http://EdWorkingPapers.com, http://afterschoolalliance.org, http://ies.ed.gov/ncee/wwc, http://wallacefoundation.org, http://rand.org, http://50stateafterschoolnetworks.org, and http://researchforaction.org. Pull the citation, sample and methodology, key findings, and any effect sizes reported. Then write a 3-page synthesis organized by theme rather than by article, in APA 7th edition style, flagging where studies disagree. Save the articles used for access by me later. Save the literature review in a .docx format using my iEval style template (uploaded).”
While some took longer, AI is still much faster than a human. With regards to task compliance, ChatGPT and Claude Cowork were out to a headstart.
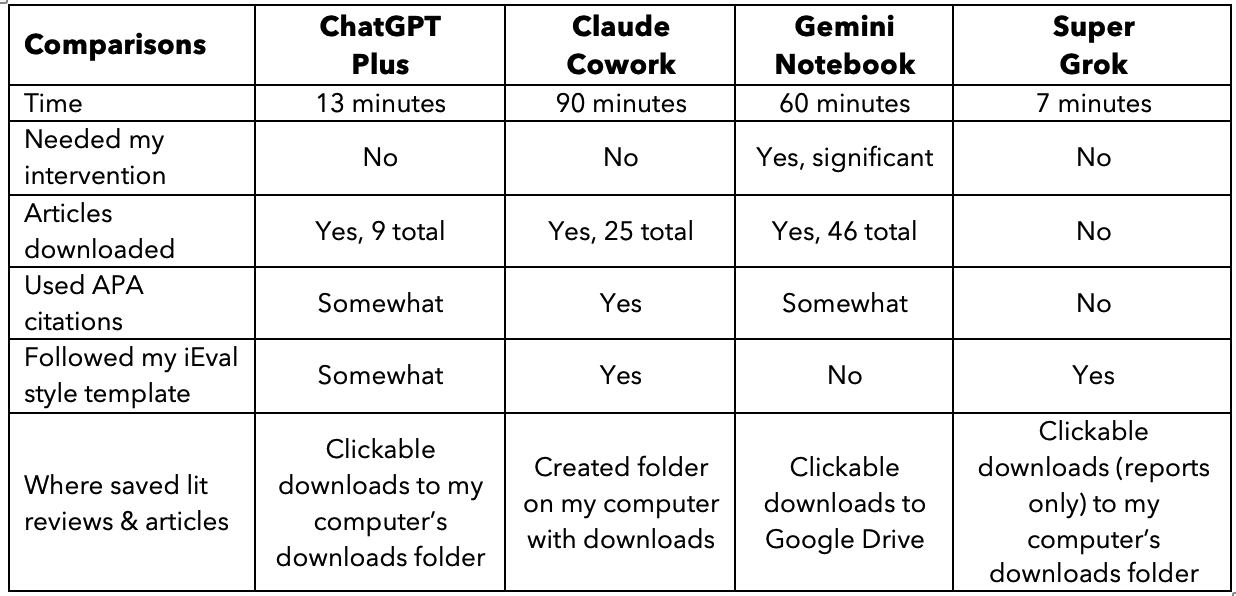
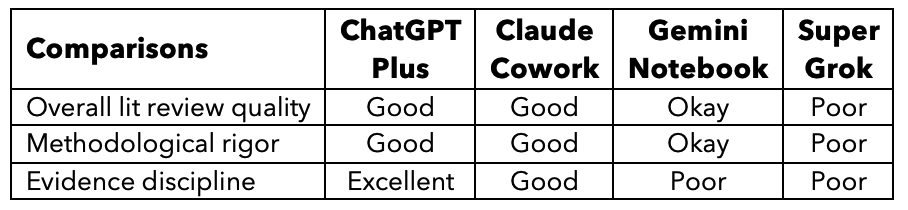
Three of the four lit reviews were useable at varying levels, but there were still issues with each of them. My biggest concerns were:
Claude wrote the entire lit review in prose, more like a synthesis and less like a traditional lit review. It also made jumps from hypotheses to confirmed conclusions without clear evidence to support that.
ChatGPT had a much more limited scope of articles from which it was pulling the information, making it a less comprehensive perspective, but what it did write was well done.
Gemini overclaimed, making assumptions that were stronger than evidence that was cited supported.
Grok did not include any reference list and included unsourced data. This is the one that I’d call an epic fail as far as a lit review goes.
When the AI models graded their own lit reviews against each of the other AI lit reviews, it was interesting to see that none of the AI models rated their own work as the best. Three of them rated the same model (ChatGPT) as the best, and that model rated another model (Claude) as best with their own as a close second. Personally, I would use a combination of the top two models since one gave an excellent synthesis (Claude) and one was better methodologically (ChatGPT) – using elements from both of them would make for a comprehensive lit review.
I also learned what I would do differently when I use AI to help with lit reviews in the future, and I can concede that I will be doing that. I will give parameters on the timeframe for articles (e.g., nothing older than 15 years) and the minimum number of citations I want (e.g., 20). I will also give permission for the model to look beyond the starting websites I gave to find other websites that meet specific qualifications (e.g., peer-reviewed, respected, cited in other research). I will also give 2-3 clear questions that I want the lit review to answer so the analysis is more focused. Two of the models shared some bullets about contradictory evidence – I liked that a lot, so I would make sure to include that in future instructions.
Here’s my revised prompt for next time (much more detailed, and AI helped me create it using the parameters I discussed above):
Conduct a comprehensive literature review on after school programs (What are the impacts of afterschool programs on youth, families, schools, and school communities? What program characteristics, practices, or levels of participation are associated with the strongest positive outcomes?).
Begin by searching the following sources: Google Scholar, ERIC, Directory of Open Access Journals (DOAJ), EdWorkingPapers, Afterschool Alliance, What Works Clearinghouse, Wallace Foundation, RAND, 50 State Afterschool Network, Research for Action. You may search additional sources when necessary to develop a comprehensive review. Additional sources should be credible research sources, such as peer-reviewed journals, government agencies, established research organizations, universities, or respected research institutes. Prioritize peer-reviewed empirical research and rigorous evaluations. Systematic reviews and meta-analyses should also receive priority when available.
Focus primarily on research published within the past 15 years. Include older seminal studies when they remain important to understanding the evidence base. Include a minimum of 20 credible sources for each literature review when sufficient relevant research exists. Do not include sources simply to reach the minimum. If fewer than 20 credible and relevant sources exist for a topic, explain the limitation. Prioritize sources for which the full text is freely available.
Organize the review around the research questions listed above rather than summarizing studies individually. Where appropriate, address: What outcomes have been demonstrated? How strong and consistent is the evidence? Which populations, settings, or program characteristics are associated with different outcomes? What practices or program components appear most strongly associated with positive outcomes? What does the evidence not yet establish? Where do studies disagree or produce contradictory findings?
For every study used, extract and retain: full APA 7th edition citation, publication year, study purpose, sample and population, sample size, research design and methodology, intervention or program characteristics (when applicable), outcomes measured, key findings, effect sizes (when reported), statistical significance (when relevant), important limitations, and URL or DOI for the source.
Distinguish carefully between correlation, association, and evidence of causation. Do not state or imply that an intervention caused an outcome unless the research design supports a causal conclusion. Do not make claims that are stronger or broader than the cited evidence supports. Identify important limitations affecting the interpretation or generalizability of findings. If studies reach different conclusions, do not resolve the disagreement yourself unless the evidence clearly supports doing so. Describe the contradictory findings and, when possible, identify methodological, population, implementation, dosage, measurement, or contextual differences that may explain them. Do not invent, estimate, or infer effect sizes, statistics, sample characteristics, findings, quotations, or citations that are not reported in the source.
Write an approximately 3-page literature review. The review should be organized thematically rather than article-by-article. Synthesize findings across studies. Identify areas where evidence is particularly strong or consistent. Clearly identify contradictory, mixed, weak, or insufficient evidence. Discuss differences in findings that may be related to study design, population, setting, program implementation, or dosage. Distinguish well-established findings from promising but preliminary findings. Avoid unsupported generalizations. Use APA 7th edition in-text citations. Include a complete APA 7th edition reference list. Include a clearly labeled section titled “Contradictory or Inconclusive Evidence” that briefly summarizes important areas where the research does not point to a consistent conclusion. Conclude the review with a section titled “What the Evidence Supports” that answers the primary research questions while carefully matching the strength of each conclusion to the strength of the available evidence.
Before finalizing the literature review: Verify that every in-text citation corresponds to an actual source. Verify that every cited source appears in the reference list and every reference-list entry cited in the review. Verify key statistics, effect sizes, sample sizes, and major conclusions against the original source. Check that no causal claims are made from correlational evidence. Check that quotations are exact and properly cited. Identify any claims for which the supporting evidence is weak, mixed, or limited. Confirm that the review answers the stated research questions rather than simply summarizing available studies.
Save the literature review as a .docx file using my uploaded iEval style template. Save or download copies of all freely available articles used in the review so I can access the original sources later. Provide a source/evidence table containing the citation, sample, methodology, key findings, effect sizes, limitations, and source link for every study included. Clearly identify any cited source that you were unable to access in full text. Do not represent an abstract, summary, search-result snippet, or secondary citation as though you reviewed the complete original article. Accuracy and appropriate interpretation of the research evidence are more important than speed. If you cannot verify a finding or source, explicitly identify it rather than making an assumption.
I was blown away at the improvements because of the updated (really long!) prompt. However, Gemini Notebook wouldn’t run the request (Maybe the prompt was too long for it to handle? Maybe the updated prompt wasn’t worded in a way that Gemini understood?). Here are a few nuanced differences in the results from the remaining three models:
ChatGPT didn’t overclaim any findings, realistically assessed the variable of dosage, and clearly explained the differences in study sizes. The report had a strong methodological statement and comprehensive evidence table.
Claude accurately adjusted its wording related to causation. It also used the largest set of sources yet was transparent about access limitations. The report itself was well-written, including balanced conclusions, clarified contradictions, and a comprehensive evidence table.
Grok included the smallest sampling of documented resources (only 8), still referenced “additional sources” without citations, and had a weak evidence table. While it’s an improvement over Grok’s first attempt, it is still not usable.
My conclusion after Experiment #2 has changed a little. I still don't think AI replaces an evaluator, but I've moved literature reviews firmly into the category of evaluation tasks where I think AI can save me substantial time. I wouldn't trust one AI model to do the entire job unchecked. My current approach would be to use the strongest model to conduct the initial review (ChatGPT), then give the results and source articles to a second AI model (Claude) and ask it to independently verify the evidence, challenge the conclusions, identify missing research, and improve the synthesis. Then the evaluator makes the final judgment. That workflow could turn days of work into hours without turning over the thinking that actually requires an evaluator.