I wanted to know whether AI could produce the same qualitative evaluation report I would, so I put four leading AI tools to the test. All of the AI tools, when asked to grade their four analyses of the same data against the report I wrote and submitted to the client, rated my report the highest. AI may be helpful, but evaluators still make the difference.
ChatGPT Plus (GTP 5.5, paid), Claude (Claude Sonnet 5, free), Gemini Notebook (Gemini 3.5, free), and SuperGrok (Grok 4.5, paid) were all given the same source material (real interview notes with fake names) and the same request*: act as an educational evaluator and produce a summary with key findings, recommendations, and a conclusion. Then I compared their outputs side-by-side with the report I actually submitted as the external evaluator. Here's what I found.
AI is fast! ChatGPT produced a draft in 30 seconds, Claude and Gemini Notebook each took about two minutes, and Grok took seven. All had elements of a competent first draft. Fast doesn’t mean accurate, though, and the issues weren't all about writing quality. While there were many differences, my biggest concerns were:
One tool named specific staff members next to direct quotes pulled from the interview data. That's a confidentiality problem in evaluation work, not a style choice. My actual report anonymized every quote.
One tool misattributed a quote to someone who was invited to an interview but never participated.
None of the four led with what was working before diagnosing what wasn't. My report opened by naming the institution's genuine relational strength before getting into the fragmented systems and inconsistent handoffs. Every AI draft went straight to the problems.
One tool elevated a single comment into a major finding, which meant something granular became vastly overstated.
One tool hallucinated a legal company name for my firm that appeared nowhere in any materials I gave it.
When the AI tools graded their own report draft against each of the other AI drafts and my submitted report, all rated mine highest and landed on a similar distinction without me prompting it: summarizing what people said is a different task from explaining what their comments reveal about how an organization actually functions. One tool put it well: interview summarization tells you what happened, evaluation tells you why it matters
Real evaluation experience shows up in the judgment calls: which detail is a footnote, which one is a finding, what must be protected, and what is true rather than what only sounds true. Clients don't hire evaluators simply to summarize interview responses. They hire us to synthesize evidence, identify patterns, connect those patterns to organizational goals, and develop meaningful recommendations that leaders can actually use.
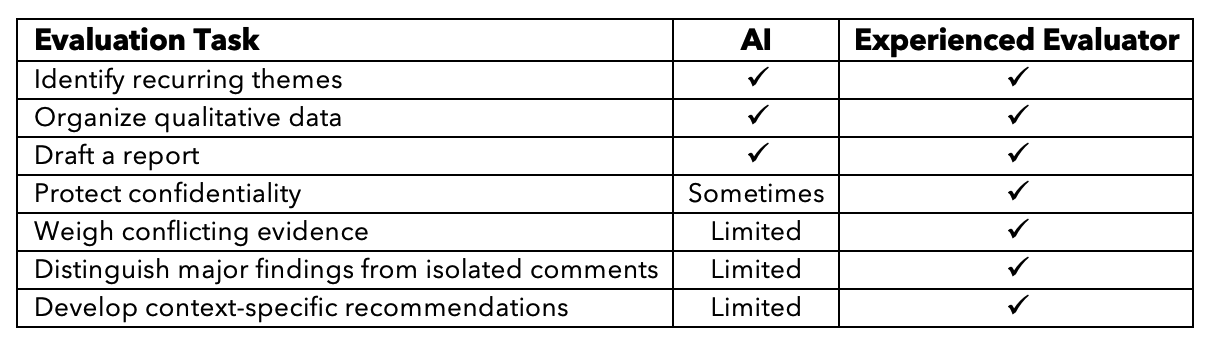
My biggest takeaway? AI can’t replace an evaluator, but it can be a helpful research assistant. It can save time organizing information, identifying recurring topics, drafting summaries, and exploring ideas. However, qualitative evaluation still depends on professional judgment. Knowing which findings matter, what they mean in context, which recommendations are supported by the evidence, and how to communicate those conclusions to decision-makers remain the work of an evaluator.
I’m curious how others are testing AI against real evaluation deliverables. What differences have you seen when the task requires synthesis rather than summary? What is most useful to you?
*Actual prompt: “The iEval team conducted phone interviews for the Title III SIP grant focusing on the current status of student interactions prior to the implementation of Navigate 360. Write up a summary of the interviews including key findings, recommendations, and a conclusion. Provide the document in an editable Word format, using a stylish and color coordinated theme (with Avenir Next as the font), and incorporating the iEval logo.”